YOUR LOGGING DETAILS STAY YOURS

Every event.
A clearer story.

A highly optimized, multi-tenant event, logging, tracing, and analytics system with security controls, compliance support, and logging metadata protection. Capture compact binary events to understand application behavior, diagnose issues, and profile UI performance while keeping internal logging details out of your shipped binary.

Windows and Linux today. macOS underway. C++ first; more languages to follow.

Server roadmap: distributed cloud, identity integrations, and intelligent diagnostics

YOUR LOGS, IN FOCUSWebsite theme
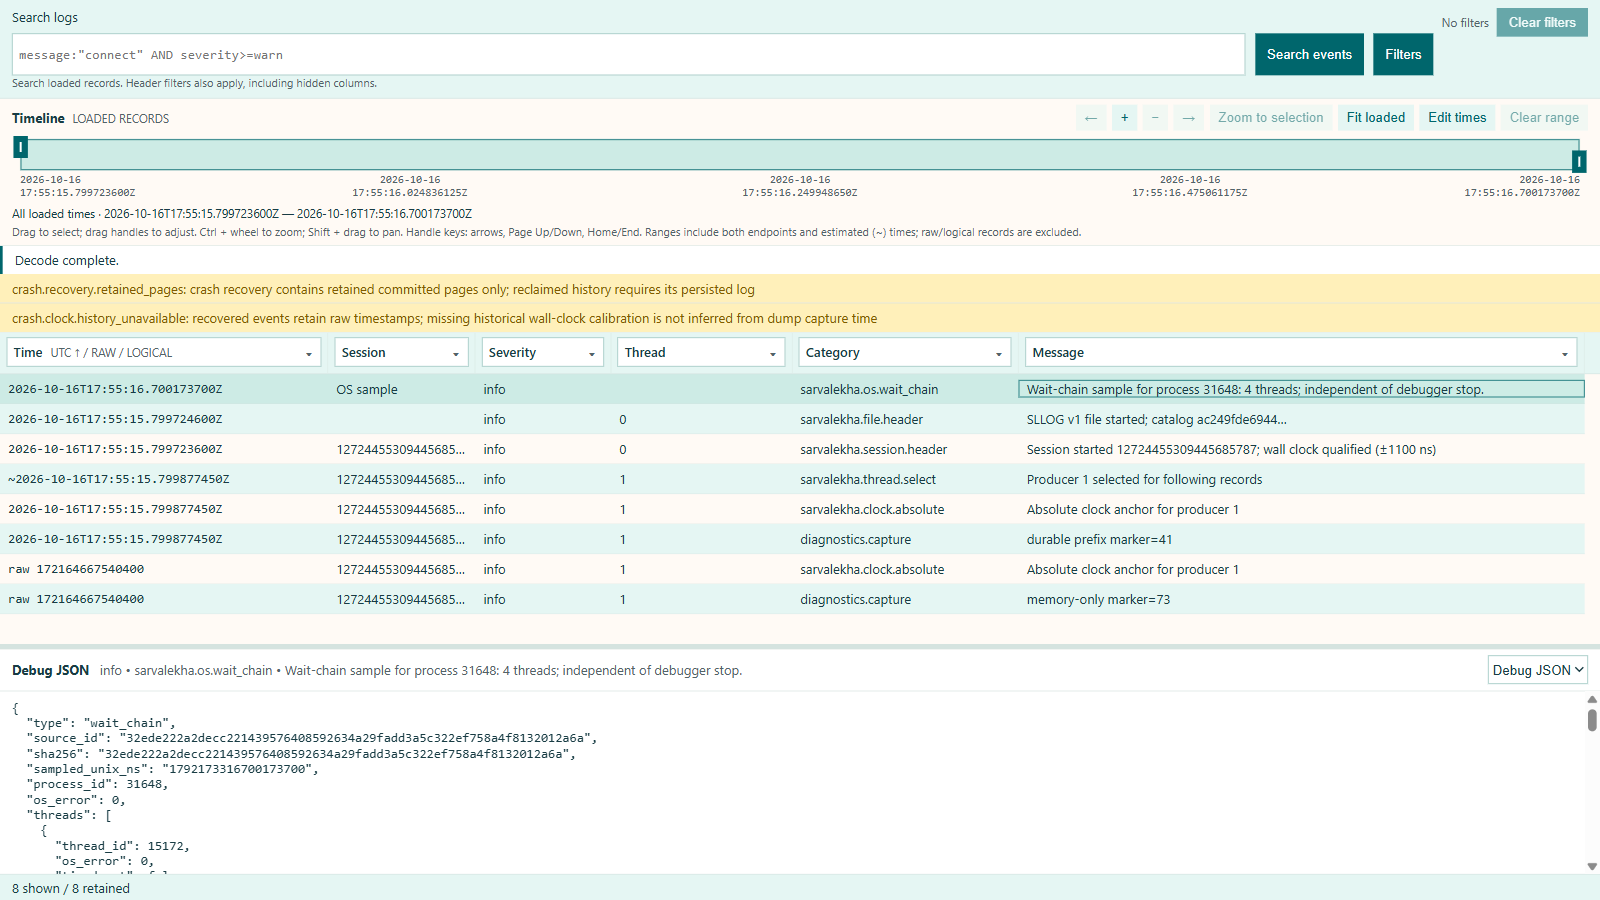
Sarvalekha desktop application with search, timeline, Session, Thread and Source columns.
Actual application · Provider-generated example logs.
Events & structured loggingTracing & correlationApplication analyticsDiagnostics & UI profiling

LOGGING DETAILS STAY OUT OF THE APPLICATION

Ship your application.
Keep its logging dictionary private.

Message text, categories, field descriptions, and source paths used only for logging live in a separate build catalog. The application records compact event IDs and values. Your users receive the application without its readable logging dictionary.

The automatic build removes the logging descriptions and verifies their absence from executable code and data. Searching those sections for the removed strings will not reveal them.

Explore logging metadata protection

ONE EVENT FOUNDATION. MANY QUESTIONS.

Understand what happened.
Discover what to improve.

From a customer issue to a slow interaction, useful answers start with useful events. Capture the values, timing, and context your team needs to investigate behavior and guide improvements.

Windows
Supported today
Linux
Supported today
macOS
Support underway
C++ first
More languages to follow
DIAGNOSTICS & SUPPORT

Make failures explainable

Follow messages and structured fields across an application session. Match evidence to its exact build and move to verified source when available.

Investigate a failed operation, an unexpected state transition, or the events leading up to a crash.

UI & PERFORMANCE PROFILING

Understand the slow interaction

Instrument application operations with spans, named events, and measured durations. Use the Viewer timeline and thread context to examine where work happens.

Record input handling, layout, rendering, or background work. Instrumentation is application-defined; automatic UI instrumentation is not included.

APPLICATION ANALYTICS

Give behavior a structure

Describe meaningful actions with named events, typed fields, and reusable context. Retain the detail needed to explore outcomes and prepare data for further analysis.

Capture workflow steps, operation results, counts, and durations. The current Viewer provides event exploration; aggregate dashboards remain a future direction.

ENGINEERING & VALIDATION

See beyond the final result

Keep diagnostic evidence from representative test runs. Search sessions, inspect exact event values, and connect a reported problem to the software that produced it.

Evaluate a release candidate or reproduce an intermittent problem with the matching catalog and retained logs.

OPTIMIZATION STARTS WITH THE DESIGN

Capture the change.
Keep the description once.

Sarvalekha separates information known at build time from values that change at runtime. That separation is the foundation of its compact event format and deferred message rendering.

Less repeated information

Static messages, field definitions, and source metadata live in an automatically generated catalog. Events carry compact identifiers, timing, and encoded values instead of repeating the full description.

Format when you investigate

The application records binary values. Readable messages are reconstructed by the decoder and Viewer, moving text formatting out of the normal capture path.

Separate capture from delivery

Per-thread buffers and a drain path separate event capture from output. The optional Helper collects native bytes and can upload completed files in the background.

Measure the difference on your workload.

Evaluate application CPU, memory, event loss, retained storage including catalogs, and decoding cost together. A focused evaluation makes the benefit concrete for your application.

Plan your evaluation


TRACING IS PART OF THE PRODUCT

Follow the operation.
Connect the evidence.

Connect application logs and events to the work that produced them. Sarvalekha brings trace identity, span lifecycles, and diagnostic context into the same compact event foundation.

SPAN LIFECYCLES

Describe how work unfolds

Create traces and parent/child spans. Record span start and end, static names, events, links, status, and errors so an operation has structure beyond a sequence of messages.

Follow a request from its entry span into a client call or a background operation. The current C++ implementation supports the static lifecycle subset.

CONTEXT ACROSS THREADS

Keep related work connected

Capture and attach context explicitly, or share a span handle with a worker thread. Trace-aware logging can select the active span; ordinary logging retains its independent capture path.

Connect work handed to a thread pool to its originating operation without treating unrelated work as part of the same span.

LOG AND EVENT CORRELATION

Bring the details into the trace

Attach trace and span identities to logs and named events. Reuse compact context records instead of repeating the complete identity in every record.

Move between operation context and the structured values that explain an outcome. Explicit context selection also supports applications with existing trace identities.

VIEWER INVESTIGATION

Inspect timing and incomplete evidence

Search trace and span IDs, inspect related loaded records, and pair span starts and ends to derive comparable durations. The span panel identifies missing endpoints, missing parents, and sequence gaps.

Current inspection is bounded to loaded evidence. Complete trace graphs, broader reconstruction, and distributed analysis are delivery roadmap items.

W3C interoperability is on the roadmap.

The identity foundation uses 16-byte trace IDs and 8-byte span IDs. Full W3C Trace Context support adds header extraction and injection, trace-state policy, and interoperability qualification. Sampling, richer tracing attributes, and catalog-aware OTLP export are also planned.

See tracing delivery status

THE EVENT WORKFLOW

Describe it once.
Make sense of it later.

Information known at build time belongs in the catalog. Values that change belong in the event. Sarvalekha brings them together when you investigate.

01

Instrument the operation

Add logs, named events, and spans to your application. Keep useful messages, structured fields, and operation context close to the code they describe.

02

Let the build connect it

The automatic build pipeline creates the catalog and event metadata. Preserve that exact catalog with the software build.

03

Follow the evidence

Open the recorded binary events with the matching catalog. Inspect messages, fields, and source context when available.

LESS TO MAINTAIN BY HAND

Easy to write.
Rich in context.

Start with a familiar logging call. Add named, typed fields when a message needs more context. Sarvalekha’s build tooling takes care of the catalog.

  • Normal application logging calls
  • Automatically generated event metadata
  • Structured fields for useful context

C++20 application interface. Integration requires a qualified build profile and runtime configuration.

application.cppC++
// A familiar application log
SLLOG_INFO(
  "worker",
  "Processing batch ",
  batch_id
);

// Add context with a named event
SLEVENT_INFO(
  "worker", "batch.completed",
  sarvalekha::field<"batch_id">(batch_id),
  sarvalekha::field<"duration_ms">(duration_ms)
);
Call-site illustration · build and runtime setup omitted

EASY TO USE. EXPLICIT TO CONFIGURE.

Familiar calls.
An automatic build workflow.

Keep instrumentation close to application code. Start with a local file and Viewer, then add collection and server access when your workflow needs them.

  1. 01

    Describe events in your code

    Write familiar severity-based logging calls or named structured events. Add typed fields and reusable context. The compiler checks supported formats, types, bounds, and declared privacy policies.

  2. 02

    Let the build maintain the catalog

    Integrate the supported provider with your build. It discovers logging sites, assigns identities, generates the matching catalog, and verifies metadata removal automatically. There is no separate message catalog to maintain by hand.

  3. 03

    Choose where events go

    Configure the runtime and output once for the application. Use a local file, a rotating file set, or the optional machine Helper. Open retained logs with their exact catalog in the desktop application or VS Code.

CONFIGURATION THAT MATCHES YOUR WORKLOAD

Start small.
Keep control as you grow.

Current integration uses build settings and explicit runtime or service configuration. Managed enrollment and a guided organization setup remain planned.

Build policy
Choose the compiled severity threshold, target-wide privacy profile, and maximum producer-page size.
Local storage
Set the output path, or use managed file rotation with segment size, retained age, total bytes, and retained-set limits.
Runtime behavior
Configure drain and durable synchronization intervals, wall-clock correlation, and optional thread metadata.
Viewer workspace
Set catalog and trusted source roots. Select columns, filters, and local folder listening for the investigation.
Shared collection
Configure the Helper destination, project scope, and certificates. With upload settings omitted, collection stays local.

C++20 application interface with a qualified compiler/provider build profile. Confirm the toolchain and packaged components for your target during evaluation.

COMPLIANCE, PRIVACY & METADATA PROTECTION

Keep internal details
under your control.

Keep readable logging descriptions in your build catalog and out of the shipped application. Decide what runtime values an event may contain, and control who receives the catalog that restores their meaning.

REMOVED FROM THE SHIPPED BINARY

Binary inspection cannot reveal removed log text

Sarvalekha extracts logging-only messages, categories, structured descriptions, and source metadata into a separate catalog. The build removes the logging contribution sections and checks the executable code and data for retained logging literals.

The descriptions are absent, rather than merely encoded inside the application. A strings scan of the verified code and data cannot recover those removed descriptions. Retain the catalog separately so your team can reconstruct readable events without distributing the logging dictionary to application users.

PRIVACY AT CAPTURE

Support compliance with sensitive-data controls

The C++ interface explicitly classifies personally identifiable information (PII), confidential data, credentials, and regulated fields. Redacted capture stores no original value bytes in the event.

Use classification and capture policies to support your data-handling requirements. Developers choose the classification and transformation. Sarvalekha does not automatically discover PII hidden in an unclassified message or value.

POLICY IN THE BUILD

Set boundaries before recording

Field policies declare permitted destinations. Build-wide privacy profiles can reject sensitive capture or narrow those declarations. These labels are not a country-aware transfer firewall. Plaintext PII has a protected-local policy; credential fields cannot request plaintext capture.

The API also supports application-supplied opaque tokens and declares keyed-hash capture. In the current minimal C++ profile, keyed hashes report unavailable without exposing the input; a working key-provider integration is still required.

SOURCE & SERVER ACCESS

Share evidence with clear boundaries

Basic decoding needs the exact catalog, not your source tree. Source navigation uses verified source identity and explicitly trusted mappings. Native log export does not implicitly include source or catalogs.

The server foundation uses certificate-authenticated workload connections and scoped read, write, and export grants. Browser access has a separate owner session. The authentication roadmap covers enterprise SSO, directory integration, local accounts, and provider-managed MFA; broader user administration remains planned.

This protection covers logging-only information. Function names retained in exports or debug symbols and strings used elsewhere in the application require separate release controls. Binary event values are not encrypted by metadata removal.

Support privacy and data-residency requirements.

Explicit classification, capture-time redaction, application-supplied tokens, and local investigation help reduce sensitive telemetry. Explore how these controls contribute to GDPR/DSGVO, German sector rules, and US healthcare, government, and defense requirements.

Explore compliance and data residency
Choose what leaves each boundary.

Logs, catalogs, source, and crash dumps are separate artifacts with different disclosure needs. Local file access, encryption at rest, key management, and collection policy remain part of your deployment configuration.

Discuss your data requirements

SARVALEKHA VIEWER

Explore the Viewer.

Explore events in a standalone application, inside VS Code, or through the server browser interface. Search, filter, and inspect the details with the catalog for the exact build.

Implemented foundation

Release packaging and supported configurations require confirmation.

Focus on the relevant events

Use expression search, column-header filters, a time-range timeline, and selectable columns. Local views search loaded records; server searches run across selected stored applications and sessions.

Connect evidence to its build

Inspect structured values, JSON, native bytes, and matching catalog metadata. Navigate to verified source when the exact source and evidence are available.

Recover the context around a crash

Read retained committed events from supported Windows full-memory dumps and Linux ELF cores with the exact catalog. Recovery depends on captured logger memory; it cannot restore reclaimed or uncommitted events.

LOCAL, ORGANIZATION & DISTRIBUTED CLOUD

A distributed architecture.
Your deployment boundaries.

Sarvalekha is designed for centralized, distributed, and hierarchical deployment. Connect local collection, organization servers, and cloud nodes around tenant ownership, access, and data-location requirements. The current preview already supports authenticated catalog routing through configured nodes.

Implemented foundation
YOUR WORKSTATION

Local Viewer

Investigate accessible logs with their matching catalogs in the desktop application or VS Code.

  • No Sarvalekha server required
  • Local files and managed log folders
  • Offline reading with retained artifacts
Explore the Viewer
Windows x64 preview
YOUR TEAM

Local Server

Collect completed native logs, search stored events, and inspect evidence through the built-in browser Viewer.

  • Resumable authenticated uploads
  • Application and session selection
  • Scoped reads and native log exports
See current capabilities
Deployment direction
YOUR ORGANIZATION

Distributed Cloud

Connect organization and cloud nodes in a multi-tenant deployment. Extend the working catalog hierarchy toward distributed investigation and coordinated operation.

  • Configured catalog routing today
  • Planned distributed search and replication
  • Planned failover and managed cloud operations
Discuss your deployment
One product, multiple deployment locations.

Use local infrastructure, organization-controlled cloud environments, or a hybrid arrangement as the deployment direction. Keep tenant ownership explicit as requests move between nodes. Distributed queries, replication, and failover are planned; a hosted Sarvalekha service is not yet generally available.

Explore the tenant model

HIERARCHICAL BY DESIGN

Find the matching catalog
across trusted nodes.

A server can hold catalogs locally or forward a lookup through an explicitly configured next hop. Each hop checks access within the configured tenant, organization, and project scope.

Illustrative catalog lookup path
  1. Central nodeReceives an authorized request
  2. Organization nodeRoutes through configured trust
  3. Development nodeReturns the exact build catalog

The same server executable can serve different roles. The configured route follows catalog ownership and can cross several levels.

The current hierarchy supports configured catalog lookup. Distributed log-query fan-out, automatic replica failover, hierarchy-wide retention, and managed enrollment remain planned.

The Helper connects application capture to shared investigation.

The Windows x64 preview collects locally and optionally uploads closed native files in the background. Interrupted transfers can resume, and local files remain available after upload. Active-file streaming and automatic server retention remain planned.

Collection & upload preview

Explore the server roadmap: symbols, crash diagnostics, and adaptive collection

Server storage uses native binary artifacts and metadata; no separate database service is required. The current service is a preview with bounded queries and storage, not a general release.


MULTI-TENANT BY DESIGN

One product.
Distinct ownership boundaries.

Multi-tenancy is part of the Sarvalekha product architecture. Organize collection, catalogs, stored logs, investigation, and exports by tenant, organization, and project, with the same ownership model extending to planned symbols, crash analysis, and AI diagnostics.

TENANT / ORGANIZATION / PROJECT

Keep customer context explicit

Associate application sessions and artifacts with their authorized scope. Teams can organize different customers, business units, and projects without treating a shared server as shared permission to read everything.

Local capture feeds the configured collection context. Tenant selection belongs in deployment and access configuration, without adding identity-provider work to normal logging calls.

ACCESS THROUGH THE HIERARCHY

Carry permissions across boundaries

The server preview checks configured scope and grants for upload, query, export, and catalog routing. A trusted peer uses its own authorized identity when resolving a catalog.

The product-wide model requires the same boundaries for caches, debug artifacts, and future distributed operations. A tenant identifier selects context; it does not grant access.

PLANNED TENANT ADMINISTRATION

Let organizations govern their data

Manage membership, roles, service identities, collection policies, quotas, retention, and audit evidence within the appropriate tenant scope.

Extend those controls to symbol services and adaptive diagnostics. Cross-client analysis is intended to stay within the authorized customer boundary.

The current preview supplies configured tenant/organization/project scope and certificate grants, with a single-owner browser session. Self-service tenant lifecycle, per-user administration, quotas, and broader distributed isolation qualification remain delivery work. Local file access also depends on operating-system permissions.

AUTHENTICATION & AUTHORIZATION ROADMAP

Use the identity
your organization trusts.

Connect users, build systems, Helpers, and server peers through the appropriate identity. Planned integrations cover enterprise sign-in, local accounts, provider-managed authentication methods, and unattended workload access.

PLANNED ENTERPRISE SSO

OpenID Connect and SAML federation

Use organizational single sign-on through OpenID Connect, with OAuth access tokens for API authorization. Include SAML 2.0 federation through a compatible identity provider or broker.

Microsoft Entra ID and other organization identity providers are integration targets. Provider configuration and qualification determine the supported sign-in profile.

PLANNED DIRECTORY INTEGRATION

Active Directory and existing directories

Connect on-premises Active Directory or LDAP-backed identities through the configured identity service. Include integrated Windows/Kerberos sign-in where the provider and deployment support it.

Directory groups can inform planned tenant/project role mapping. Directory membership alone will not bypass Sarvalekha resource permissions.

PLANNED LOCAL & PROVIDER ACCOUNTS

Local accounts and Firebase Authentication

Support local username/password accounts through a maintained identity component, plus Firebase Authentication as an external integration target.

Provider-enabled email/password, email-link, and social sign-in are part of the integration scope. Enterprise OIDC/SAML through Firebase requires Identity Platform; provider capabilities and configuration apply.

PLANNED STRONGER SIGN-IN

MFA, passkeys, and security keys

Use the configured identity provider to apply multi-factor authentication, passwordless/passkey sign-in, and security-key policies where supported.

Qualify session expiry, logout, revocation, and recovery with each integration. These are provider-mediated capabilities, not built-in authentication methods available today.

WORKLOAD FOUNDATION & ROADMAP

Separate identities for automation

Certificate-authenticated workload access exists for Helpers and server peers. Keep build publication, uploads, queries, and exports scoped to the operations each identity needs.

Planned additions include service-account access, OAuth client credentials or workload federation, short-lived credentials, and managed enrollment/rotation. Background services must not depend on a developer staying signed in.

PLANNED USER ACCESS MANAGEMENT

Sign in once, receive authorized access

Discover the trusted server configuration, sign in, and choose among authorized projects. Map identities and groups to tenant, organization, project, and operation permissions.

Keep catalog and log upload/read grants separate, with additional controls for administration, debug artifacts, symbols, and source. Repository access remains independently governed.

Match the sign-in method to the deployment.

Local-account operation is planned for local servers without an external identity dependency. Federated sign-in follows the availability and policy of its provider. Today, browser access uses a separate owner session and workload connections use certificate grants; the broader integrations above remain planned.

Discuss identity and tenant requirements


SARVALEKHA SERVER ROADMAP

From a crash report
to the next useful answer.

Extend the distributed, multi-tenant server architecture with identity integrations, symbol services, crash evidence, and intelligent diagnostics. Our direction is faster customer resolution through better evidence, clearer prioritization, and targeted collection across client installations.

Distributed cloud and identity foundations.

Expand tenant administration, enterprise sign-in, and workload enrollment alongside distributed search, replication, and failover. Carry authorization and data-handling policy through the hierarchy as new diagnostic services are introduced.

Explore planned authentication support

HIGH-PRIORITY DELIVERY

Recover logs from crash evidence

Make the events leading up to a failure available in a dependable customer investigation workflow. This is the first priority for the diagnostics roadmap, building on existing retained-log recovery.

The current foundation reads retained committed events from supported Windows x64 full-memory dumps and Linux x86-64 ELF cores with the exact catalog. We will qualify the customer workflow and its server integration. Small minidumps may omit logger memory; missing, reclaimed, or uncommitted events cannot be reconstructed.

PLANNED SYMBOL SERVER

Find the exact build artifacts

Extend catalog services to native debug symbols and source references. Match crash evidence to the application build and make the right artifacts available to authorized investigation tools.

Delivery scope includes supported symbol formats, lookup protocols, debugger integrations, access controls, caching, and retention.

PLANNED ADVANCED DIAGNOSTICS

Make crash investigation more intelligent

Bring dumps, recovered logs, symbols, and source context together. Group related failures, examine the available evidence, and identify what is missing before choosing the next diagnostic step.

Preserve the distinction between observed facts, diagnostic hypotheses, and unavailable evidence. Expanded crash analysis builds on the recovery foundation.

PLANNED ADAPTIVE AI DIAGNOSTICS

Learn what the next crash should capture

Coordinate client-side AI diagnostic components with server analysis across authorized client installations. Prioritize recurring failures by impact and evidence, then propose the additional information needed to investigate them.

Apply an approved, targeted capture profile on eligible clients so the next matching crash can supply more useful evidence and help reduce customer turnaround time.

PLANNED WORKFLOW / AN INSUFFICIENT MINIDUMP

A shipped bug crashes a client. The next report can tell us more.

  1. 01

    Receive the report

    The server receives a minidump and matches it to the exact application build and a related incident.

  2. 02

    Identify the gap

    Analysis finds that an approved diagnostic value, thread context, or relevant memory region was not captured.

  3. 03

    Target the next capture

    A customer-authorized policy selects the additional evidence, eligible clients, resource limits, and expiry.

  4. 04

    Improve the investigation

    The next matching crash captures the permitted evidence and attaches it to the incident for further analysis.

This feedback loop is planned. It cannot restore data absent from the original dump. Collection must stay within customer permissions, tenant boundaries, privacy and residency policies, and explicit resource limits. AI recommendations do not establish a verified root cause.

Plan the diagnostic workflow with us.

Agree target platforms, dump profiles, symbol formats, client rollout controls, and measurable investigation outcomes. Delivery milestones will distinguish crash-log recovery from symbol services and adaptive collection.

Discuss the server roadmap

A CLEAR VIEW OF THE PRODUCT

Capabilities and
the delivery roadmap.

Plan around the full product direction, from events and tracing to compliance support, symbol services, and crash analysis. Agree the delivery scope, milestones, target platforms, and acceptance criteria for your application.

Capability status reviewed against the repository on 23 September 2026. Implementation status is not general release availability.
CapabilityCurrent statusScope
Operating systemsWindows and LinuxSarvalekha supports Windows and Linux today. macOS support is underway; component-specific qualification varies.
Events, logging, tracing, and analyticsC++ foundation; scope variesTyped events, structured logs, reusable context, static trace/span lifecycles, correlation, and native binary recording. Additional languages follow C++ readiness.
Compliance support through PII and sensitive-data controlsImplemented foundationSupport data-handling requirements with explicit classification, redaction, declared destinations, and build-wide privacy policies. Geographic transfer enforcement is not implemented. Keyed-hash capture needs a working key-provider integration.
Logging metadata protectionImplemented foundationReadable logging descriptions stay in a separate catalog. The build removes logging-only text and metadata and checks executable code and data for retained literals.
Local output and configurationImplemented foundationFile sinks, managed rotating sets, retention controls, compiled severity, and runtime drain settings.
Desktop and VS Code ViewerImplemented foundationSearch, header filters, column selection, timeline, structured details, binary inspection, and verified source navigation.
Recover logs from crash evidenceHigh-priority delivery; foundation existsBuild on retained committed-log recovery from supported Windows x64 full-memory dumps and Linux x86-64 ELF cores. Qualify the customer workflow and server integration; small minidumps may lack logger memory.
Helper and server collectionWindows x64 previewLocal collection, resumable closed-file uploads, native storage, scoped access, and immutable exports.
Server browser ViewerWindows x64 previewSearch stored events across applications and sessions, inspect details, and select available trace/span context.
Product-wide multi-tenancyScoped foundation; administration plannedTenant/organization/project ownership across collection and investigation, extending to future diagnostics. Configured scope and certificate grants exist; self-service lifecycle, per-user administration, and quotas remain planned.
Distributed cloud architectureCatalog routing preview; broader delivery plannedCentralized, distributed, and hierarchical deployment direction. Distributed log queries, replication, automatic failover, coordinated retention, and managed cloud operation remain planned.
Authentication integrationsCertificate/owner-session foundation; integrations plannedEnterprise OIDC/SSO, SAML federation, Entra ID/AD, LDAP and provider-backed Kerberos, Firebase Authentication, local accounts, provider-managed MFA/passkeys, and workload federation. Qualification depends on the selected provider and deployment.
Hierarchical catalog accessImplemented previewAuthenticated catalog lookup through explicitly configured nodes. Distributed queries and replica failover remain planned.
Tracing and log correlationStatic lifecycle implemented; broader work plannedRoot/child spans, cross-thread context, correlated logs, static span events, links, status/errors, and bounded lifecycle/duration inspection.
W3C Trace Context interoperabilityPlanned; compatible identity foundation exists16-byte trace IDs and 8-byte span IDs exist. Header extraction/injection, tracestate policy, and interoperability qualification remain delivery work.
Distributed tracing and telemetry exportPlanned completionExpand the static lifecycle foundation with richer attributes, sampling, graph reconstruction, and catalog-aware OTLP export.
UI and performance profilingApplication-instrumented foundationInstrument operations and durations; inspect event timing and thread context. Automatic UI instrumentation remains future work.
Symbol server supportPlannedExtend catalog services to exact-build native symbols and source references, with access controls and debugger integration. Protocols and supported formats need qualification.
Expanded crash analysisPlanned; crash-log recovery existsBring crash evidence, matching build artifacts, symbols, and source together for deeper investigation. Current recovery covers retained committed events in supported dumps and cores.
Adaptive AI-assisted crash diagnosticsPlannedCoordinate server analysis and client-side diagnostic components, prioritize related failures, identify missing evidence, and request approved additional capture on the next matching crash.
Analytics workflowsEvent foundationNamed events and typed values for analysis. Aggregate dashboards and a dedicated analytics query engine are not currently provided.
Managed organization deploymentPlannedFederated sign-in, managed enrollment, server retention administration, and hosted-service arrangements.
More languagesPlannedAdditional language support follows readiness of the C++ foundation.

A FEW PRACTICAL QUESTIONS

Before you begin.

Useful details for the first technical conversation.

Which languages and platforms does Sarvalekha support?

Sarvalekha supports Windows and Linux today, with macOS support underway. C++ is the first supported language; additional languages will follow readiness of the C++ foundation. Platform qualification varies by component: the current server and Helper preview is qualified on Windows x64.

Do I need a server to read my logs?

No. The desktop application and VS Code extension can inspect accessible logs with their exact matching catalogs. Local investigation works independently of the server. Add a server when you need shared collection, stored-event search, or configured catalog hierarchy access.

How much setup does application logging need?

Developers write supported C++ logging calls. The build tooling generates catalogs and per-call metadata automatically. Integration still requires a qualified toolchain and runtime/sink configuration. You do not maintain a handwritten message catalog.

Do I need the source code?

Basic decoding needs the matching catalog, not the application source. Navigation to source additionally needs accessible, verified source and the appropriate evidence.

Can our team work offline?

Local investigation can work offline when the required logs and matching catalogs are already available. Under the target distribution policy, development binaries supplied to customers for testing require exact catalog publication to the configured cloud destination before handoff. That publication workflow remains planned; a fully isolated customer-test distribution exception is not established.

Will Sarvalekha reduce our logging costs?

The design separates static descriptions from changing values and defers readable message formatting. Actual CPU, memory, storage, and investigation results depend on your workload. Evaluate the complete workflow, including decoding and retained catalogs; no universal performance result is promised.

Does binary logging automatically protect PII?

No. Developers must classify sensitive fields and select their capture policy. Redaction omits the original value from the event, and build-wide profiles can restrict capture. Binary encoding alone does not encrypt data or discover PII. The current minimal keyed-hash profile reports unavailable rather than recording the input when no key provider is installed.

Can someone find our log messages by searching the application binary?

Sarvalekha removes logging-only message text and metadata from the shipped executable and keeps the descriptions in a separate build catalog. The automatic build verifies their absence from executable code and data. A binary string search of those sections cannot recover the removed logging descriptions. Your team reconstructs readable events with the exact catalog, which can be retained separately from the application.

Does this hide every function name and application string?

The guarantee covers logging-only information removed by the provider. Function names in exported symbols or debug information, and strings used independently by application code, require separate release-packaging controls. Keep catalogs and debug artifacts under the intended access policy. Runtime event values still need appropriate privacy controls.

Can we use Sarvalekha for analytics and UI profiling?

Yes. Instrument meaningful actions and durations with named events and typed fields, then examine their timing and context. These are application-instrumented workflows today. Automatic UI instrumentation, aggregate dashboards, and a dedicated analytics query engine are not included in the current foundation.

Does Sarvalekha support tracing and W3C Trace Context?

The C++ foundation creates traces and parent/child spans, records lifecycle events, supports cross-thread context, and correlates logs with spans. It uses 16-byte trace IDs and 8-byte span IDs. Full W3C Trace Context header extraction and injection, bounded tracestate handling, and interoperability qualification are planned; compatible identities alone do not establish W3C conformance.

Will Sarvalekha support a symbol server and crash analysis?

Yes. The roadmap extends the catalog service to build-associated native symbols and source references, alongside expanded crash-analysis workflows. Today, the Viewer can recover retained committed log events from supported Windows x64 full-memory dumps and Linux x86-64 ELF cores with the matching catalog. Full symbol-server protocols, debugger integrations, and broader crash analysis remain delivery work.

How does Sarvalekha support compliance requirements?

Explicit PII and sensitive-field classifications, redaction, permitted destinations, build-wide capture policies, and scoped server access help teams enforce their data-handling requirements. Compliance depends on the applicable requirements and deployment; these controls do not imply certification or automatic compliance.

Can Sarvalekha keep sensitive logs within a country or region?

Local capture and offline investigation let you work with retained logs and catalogs without a remote log service. The Helper uploader is optional. Operators must choose approved infrastructure, recipients, backups, and hierarchy nodes, and control network egress and remote access. Destination labels are not automatic geographic enforcement, and native-file uploads do not sanitize individual fields.

Does redaction make our logs anonymous or automatically compliant?

Redacted capture omits the original field value, but other fields and context can still identify a person. Opaque tokens and hashes do not automatically establish anonymisation. Compliance also depends on lawful processing, transfer mechanisms, access, retention, and deployment controls; review the complete artifact before sharing.

How will adaptive crash diagnostics work?

The planned server workflow analyzes a crash report, identifies missing evidence, and proposes a targeted capture profile for eligible clients. Within customer-approved permissions and limits, the next matching crash can collect that additional information. AI-assisted prioritization and analysis aim to shorten investigation time; they cannot recover data missing from the first dump or guarantee a root cause.

Is Sarvalekha multi-tenant?

Yes. The product architecture uses tenant, organization, and project boundaries across collection, catalog resolution, stored logs, investigation, and exports, extending to planned symbol and diagnostic services. The current server preview enforces configured scope and certificate grants. Per-user and self-service tenant administration, quotas, and broader distributed isolation qualification remain delivery work.

What is the distributed cloud direction?

Connect development, team, organization, and cloud nodes through a distributed server architecture. Configured catalog routing is implemented in the preview. Distributed log queries, replication, automatic failover, coordinated retention, and managed cloud operations are roadmap capabilities, with placement and access designed around each customer boundary.

Which authentication methods are planned?

The roadmap covers OpenID Connect SSO, SAML federation, Microsoft Entra ID, Active Directory and LDAP integration, provider-backed Windows/Kerberos sign-in, Firebase Authentication, and local accounts. Provider-managed email links, social sign-in, MFA, passkeys, and security keys depend on the selected identity service. Workload access will add service identities, short-lived tokens, and managed enrollment to the existing certificate foundation. Each integration must be qualified before availability is claimed.

What does the server hierarchy do today?

Configured servers can resolve exact catalogs through trusted nodes, with scope checks at each hop. A central node, organization node, and development node can cooperate without each storing a catalog copy. Distributed log searches, automatic failover, and managed organization enrollment remain planned.

Are the server products available now?

A Windows x64 server preview implements catalog hierarchy access, resumable completed-file uploads, native storage, event search, and a browser Viewer. It uses explicit certificate grants and a separate browser owner session. Managed organization sign-in, distributed queries, and a hosted cloud offering remain planned. Confirm packaging and support for your deployment.

START WITH ONE APPLICATION

Understand your
application.
See where to improve.

Choose a representative component and a tracing, diagnostics, crash investigation, UI profiling, analytics, or logging use case. Prepare the context for a focused evaluation discussion.

Your evaluation brief

A short starting point for your team.

  1. 01
    The application

    Platform, compiler, build system, and C++ mode.

  2. 02
    The problem

    Trace correlation, UI performance, crash evidence, sensitive-data handling, or logging cost.

  3. 03
    A useful outcome

    A representative workload and measurable success criteria.

Download the brief

Editable text checklist · no sign-up required

LET’S TALK ABOUT SARVALEKHA

Start a conversation.

Discuss your application, plan an evaluation, or explore your event, logging, tracing, analytics, compliance, symbol server, crash analysis, and deployment requirements.

Rohit Jairaj Singh
Visit my homepage